AI quality evaluation platformBuild AI products
you can trust

Turn AI quality from a subjective assessment into a measurable, repeatable process, transparent to the whole team.

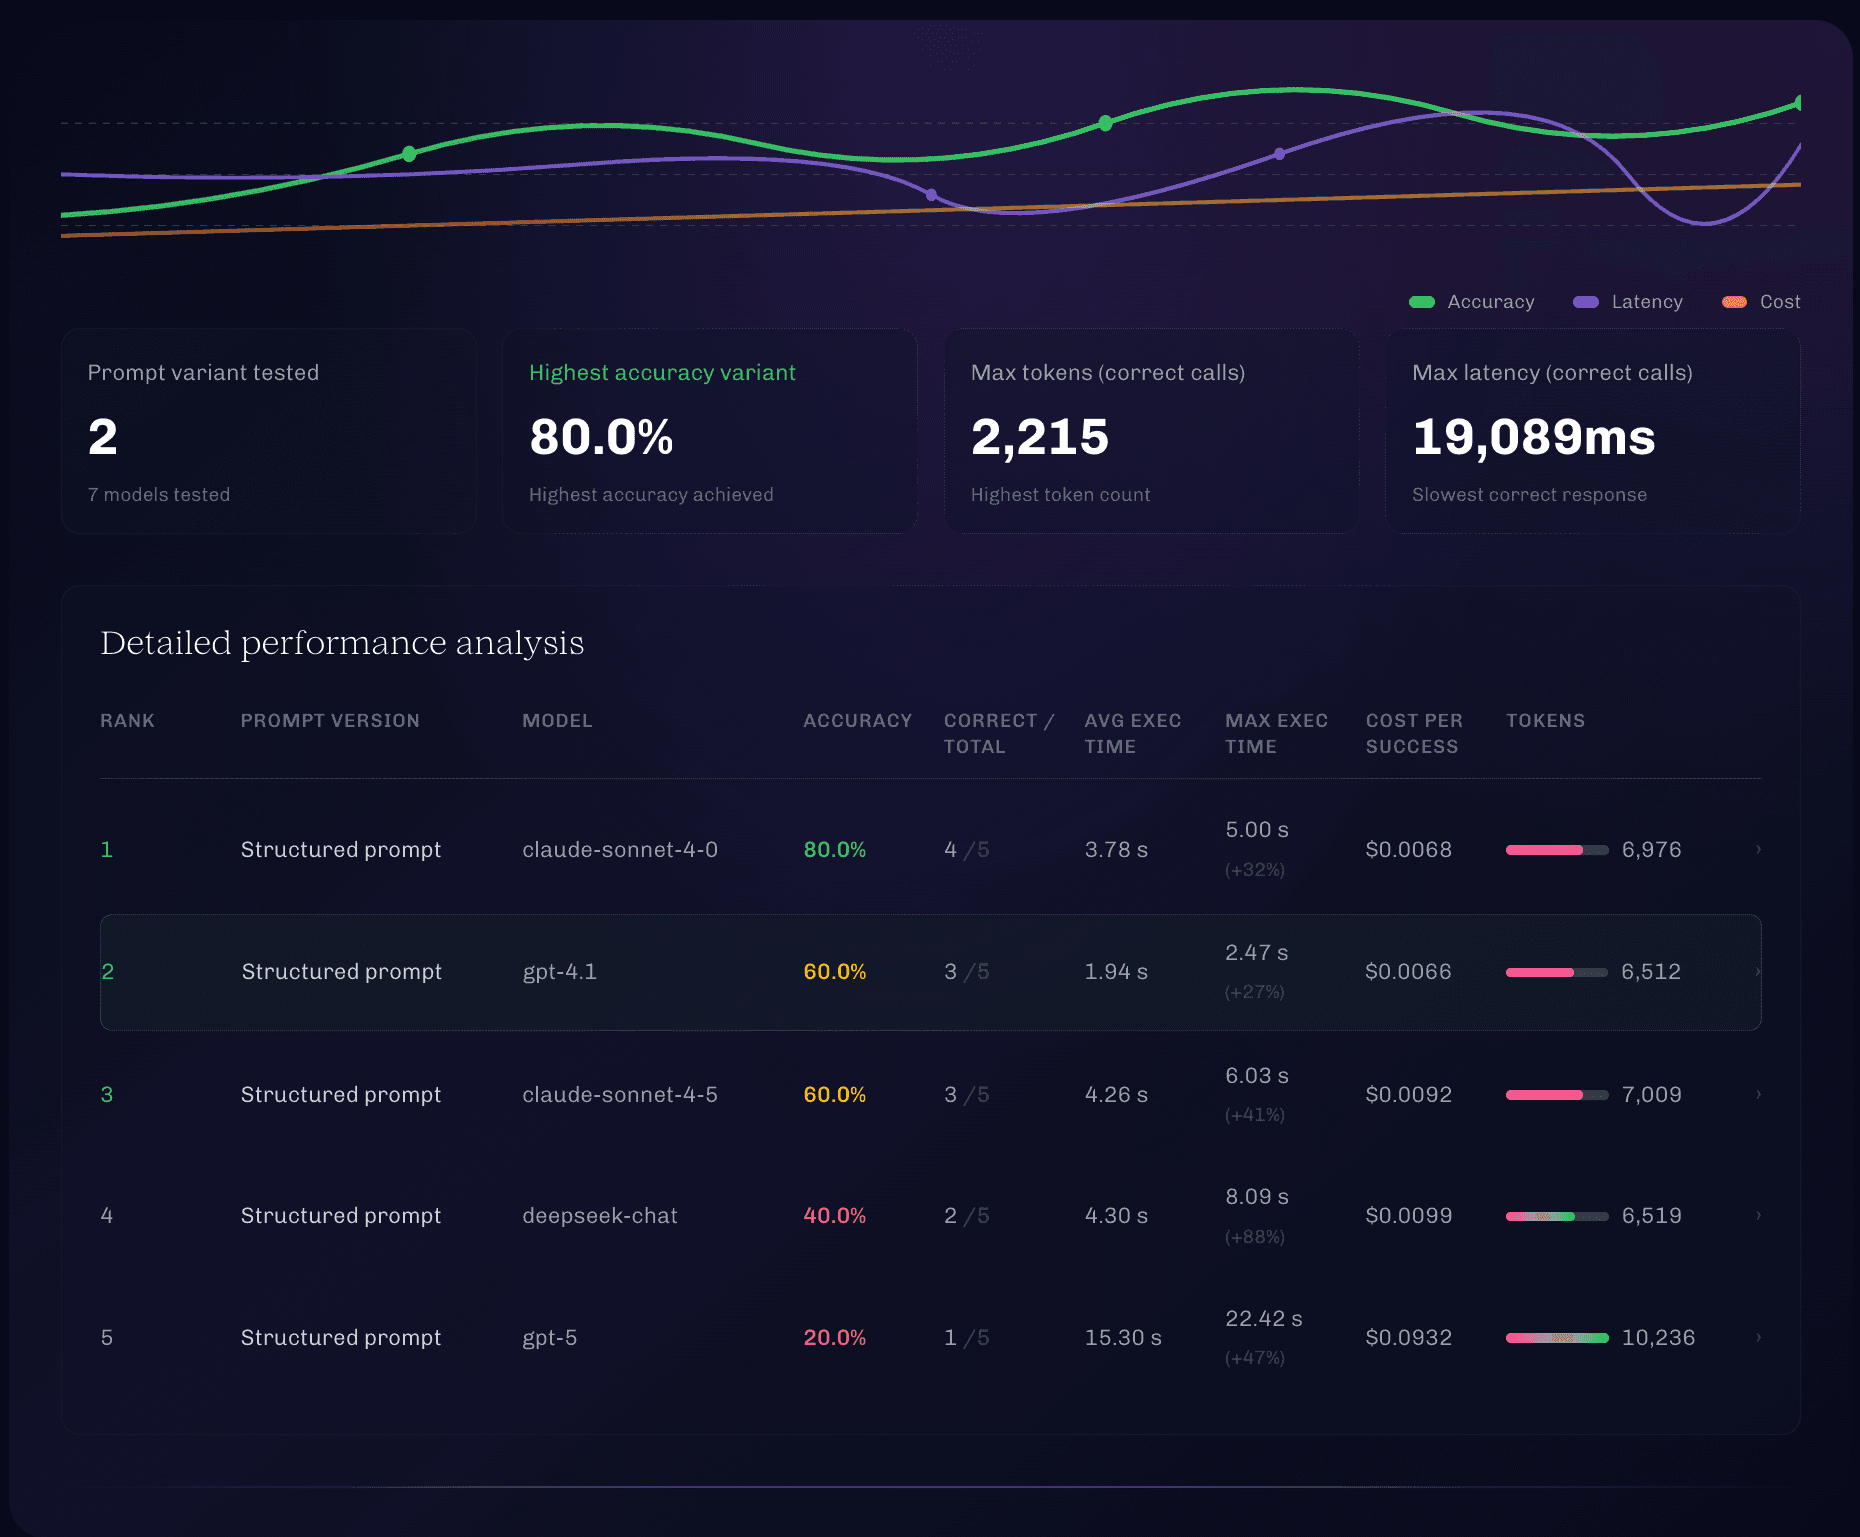
Lovelaice AI quality evaluation dashboard for product teams

Trusted by teams shipping AI in production

  • Operations1
  • AI Sentinel
  • LeanOnMe
  • Wittlinger
  • GetMarketing
Silent failures

Your AI doesn't fail loudly.
It fails quietly, while users churn.

Most AI failures have no error log. No alert. Just a feature that quietly underperforms while users quietly leave.

The people who know what good looks like are locked out of testing and validating AI quality, because it defaults to engineering.

Ship & pray isn't a strategy.

Acceptance criteria were written for software that does the same thing every time. An AI feature doesn’t, so the usual checks leave gaps. These are the gaps teams describe to us.

"It's on the roadmap."

You've been waiting on engineering for two quarters. Every AI idea needs a ticket, a sprint, a review. The ideas pile up. The shipping doesn't.

"We vibe-checked it. It's probably fine."

You tested three happy cases and shipped. You'd rather not find out what broke from a customer complaint.

"Let’s try rewording the prompt again."

Three weeks of tinkering, no record of what changed what. Every fix risks breaking something that worked yesterday, and nobody can prove it didn’t.

"We upgraded the model. Then the complaints started."

You found out a month later, from users. There was no alert, no comparison, no process. Just inbox messages and a very uncomfortable sprint review.

01Catch

Catch it
before it ships.

Pipeline · Customer-queries · v3
Running

Failure clusters found

412 / 412 evals
Invoice fields · wrong schema18 hits
18
Multilingual · answered in English6 hits
6
Refund tone · too clinical3 hits
3
Greeting drift · off-brand2 hits
2
29 failures · ClusteredReport ready · 2m 14s

Most teams test a handful of cases that already work. Lovelaice runs evals across your full dataset, clusters the failures, and hands you the short list of what actually breaks.

100+test cases ran
24failure groups
2mavg run time
See how it works →
02Validate

Prove it
moves the number.

Experiment · Compare · Head-to-head
Live

Head-to-head on your data

Same prompt · Same 127 cases

Current · GPT-4.1
47%
$2.90/k · 2.1s
→
Candidate · Sonnet-4.5
$2.10/k · 1.4s
Accuracy
+42pt
Cost per call
-27%
Latency
-33%
Validated · 412 runsRecommend → Sonnet-4.5

Every prompt tweak and model swap gets a before/after score on the same test set. No more shipping a change and hoping the complaints stop.

+42ptaccuracy gap found
27%cost saved
1click to deploy
See how it works →
03Own

Own the
quality story.

Quality · Release-trail · Q2
Fresh

Quality over time

92.4% now

Factuality · Last 8 releases

Accuracy
↑ 14pt vs baseline
Spend
$13.8K
1.3k calls · $0.01
Latency
1.2s
p50 · steady
Release 04-12 · -4.2%
Auto-exports
PDFCSVNotion

An AI feature that passed in March does not necessarily behave the same in April. Models update, prompts drift, data changes. Lovelaice re-scores every release against the same test set, flags the regression the moment it lands, and keeps the trail: exportable, timestamped, defensible. PMs read it without asking engineering.

-4.2%regression caught
12min to export
0eng tickets
See how it works →

Not sure where to start?

Take our 3-minute AI evaluation quiz and get a personalized report on your team's AI maturity level and how it compares to our benchmarks.

Take the quiz
Teams using Lovelaice

Built for real impact. Used by great teams.

Real teams · Real results
Anian Ziegler

Anian Ziegler

Co-Founder & CPTO, Operations1

Daniel Kurt

Daniel Kurt

Founder, AI Sentinel

Albert Cristea

Albert Cristea

Director of products

See Lovelaice run in real workflows.

See how product teams test AI models on their own data, compare results and catch failures, all in one shared evaluation workspace.

  • ✓Test AI ideas using real data
  • ✓Compare multiple models instantly
  • ✓Gain automated performance insights
  • ✓Share validated knowledge across teams
03:12 · walkthrough
comparison

Stop guessing.
Start knowing.

Ship & hope

  • ×Passed the demo once, assumed it still works
  • ×Engineering runs the evals, sends PMs a summary
  • ×Pick Opus 4.7 because "it's the best"
  • ×Test 3–10 happy path examples
  • ×Find out what broke from user complaints
  • ×Paying up to 100x for models without benchmarking
  • ×Learnings in scattered Slack threads

With Lovelaice

  • ✓Re-measured on the same test set after every change
  • ✓The PM team that owns the outcome runs the measurement
  • ✓Compare 10+ models on your actual data
  • ✓Evaluate across hundreds of real test cases
  • ✓Catch failures before deployment, scale manual testing
  • ✓Know your actual cost per use case before you commit
  • ✓Run hundreds of test cases without time limits, every time.
Three steps to shipping proven AI

Three steps. Not a two-quarter project.

Upload, evaluate, decide. Before any engineers are involved.

Bring the data you already have.

Your traces, prompts, real inputs and your experts’ definition of a correct answer. Re-use everything you already have.

Run everything, then see the failures.

Every prompt or model change is scored on the full set. Failures are grouped into patterns, so you learn why it broke, not only that it did. The cause is rarely the one you assumed.

Hand over a proven configuration.

Engineering gets accuracy, cost and latency on the record, plus the test set that keeps it there.

Real AI products. Real numbers.

How product teams use Lovelaice to turn live AI products into measured, reliable systems.

— Eval setup & optimization

52% to 88% accuracy. Three weeks.

Measurable quality uplift on the model they were already running — starting from zero baseline.

Read the case study →
— Eval setup & optimization

18% to 93% accuracy. 25 experiments.

Production-ready agent on GPT-5 Mini at 93% accuracy — on a cheaper model than any earlier attempt.

Read the case study →
— Eval audit & optimization

The failure no one was looking for.

A systematic multi-run pattern analysis surfaced a consistent bias in a validated golden set.

Read the case study →

FAQ,
briefly.

Still on the fence? Here's what most teams ask before their first eval run.

About Lovelaice and independent recognition

The AI quality platform for product teams.

Define what good looks like for your AI feature, measure it on real data, and improve it with your domain experts in the loop, no code required. Teams have gone from 52% to 88% accuracy in under three weeks.